AI-Based Image Caption Generator using BLIP and Deep Learning
Objective
To develop an AI-based image caption generator using the BLIP model that automatically generates meaningful descriptions for images in real time, improving image understanding and accessibility.
Abstract
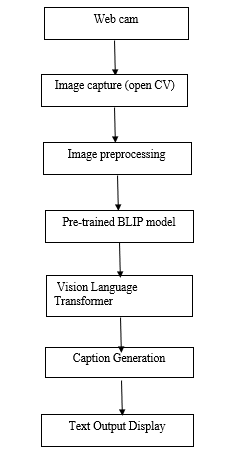
Image caption generation is an artificial intelligence technique that combines computer vision and natural language processing to automatically describe the content of images. This project presents an AI-based image caption generator using the BLIP (Bootstrapping Language-Image Pre-training) model and deep learning. The system captures live images through a webcam and generates meaningful textual descriptions using a pre-trained transformer-based vision-language model. The implementation uses OpenCV, Python, and the Hugging Face Transformers library for processing. The proposed system eliminates the need for additional training datasets and provides efficient image understanding for applications such as visual assistance, surveillance, and human-computer interaction. By utilizing advanced deep learning algorithms, the system can recognize various objects, scenes, and relationships within an image to produce contextually relevant captions. The capability enhances its usability in interactive applications where instant visual interpretation is required. This approach improves accessibility for visually impaired users and supports intelligent systems that require automatic image analysis. The developed model offers a simple, accurate, and efficient solution for real-world image captioning applications.
NOTE: Without the concern of our team, please don't submit to the college. This Abstract varies based on student requirements.
Block Diagram
Specifications
Hardware components:
- Web Camera
- Computer/Laptop
- CPU (Processor)
Software components:
- Python
Learning Outcomes
Learning outcomes:
- Understanding of Artificial Intelligence
- Knowledge of Deep Learning Concepts
- Understanding of Computer Vision Techniques
- Learning Natural Language Processing
- Knowledge of Transformer-Based Models
- Experience with BLIP Model Implementation
- Image Processing Skills
- Python Programming Proficiency
- Working with OpenCV and PyTorch
- Integration of Vision and Language Models
- Development of AI-Based Applications
- Understanding of Image Caption Generation Systems


 Paper Publishing
Request Call Back
Would you like to receive a free callback now?
Choose the best time for callback:
Leave your message and we will contact you as soon as possible
6-2-85/B, Old Maternity Hospital Road, Thyagaraja Nagar, Tirupati, Andhra Pradesh – 517501
+91 9030333433
+91 9393939065
0877-2261612

Disclaimer - Takeoff Edu Group Projects are not associated or affiliated with IEEE in any way. The IEEE Projects mentioned here are mentioned in the context of student projects, whose ideas are derived from IEEE publications, not projects of or by IEEE.